Qwen Image
Alibaba's 20B open-weights image foundation model — best-in-class text rendering (especially Chinese) with a dual-encoding architecture built for precise editing.
curl https://api.venice.ai/api/v1/image/generate \
  -H "Authorization: Bearer $VENICE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen-image",
    "prompt": "A serene mountain lake at dawn, photorealistic"
}' --output image.pngOverview
What is Qwen Image
Qwen Image is Alibaba's 20B MMDiT text-to-image foundation model, released in August 2025 under the Apache 2.0 license. It specializes in complex text rendering — multi-line layouts, paragraph-level semantics, and Chinese characters — and its dual-encoding design (Qwen2.5-VL plus a VAE) was built for precise, consistent image editing.
Using it anonymously on Venice
On Venice, Qwen Image runs under the anonymized privacy tier: your prompts are not stored, profiled, or used for training, and generations are tied to no personal history. Because the weights are open under Apache 2.0, the same model you use privately here is one you could self-host — but Venice gives you the zero-retention convenience without managing a GPU. At a flat $0.03 per image plus cheap 2× and 4× upscaling, it sits in Venice's highest-quality image tier.
Specifications
Datasheet
- Maker
- Alibaba (Qwen Team)
- Modality
- Text-to-image (a separate Qwen-Image-Edit checkpoint handles editing)
- Open weights
- Yes — Apache License 2.0
- License
- Apache License 2.0
- Prompt limit
- 2,048 chars
- Released
- August 4, 2025
- Architecture
- 20B MMDiT diffusion transformer with Qwen2.5-VL dual encoding (semantic + reconstructive)
- Parameters
- 20B
- Aspect ratios
- 1:1, 3:2, 16:9, 21:9, 9:16, 2:3, 3:4, 4:5
- Privacy on Venice
- Anonymized — prompts not stored
- Available on Venice since
- Jan 2025
Assessment
Strengths and limitations
- Best-in-class in-image text rendering: multi-line layouts, paragraph-level semantics, and fine-grained detail in both alphabetic scripts and logographic languages — Chinese is a particular standout.
- Fully open weights under Apache License 2.0, so it can be self-hosted, fine-tuned, and used commercially without licence restrictions.
- A 20B MMDiT backbone with dual Qwen2.5-VL/VAE encoding, trained with a progressive text-rendering curriculum — the architecture was designed for typography, not bolted on.
- State-of-the-art benchmark results across GenEval, DPG, OneIG-Bench (generation) and GEdit, ImgEdit, GSO (editing) per the official technical report.
- Positioned in Venice's highest-quality image tier at a flat $0.03 per generation with inexpensive 2× and 4× upscaling.
- Venice does not classify Qwen Image as uncensored — it runs with standard content filtering, unlike some open models on the platform.
- The 2,048-character prompt limit is tighter than several closed rivals, which matters for long, text-heavy layout briefs.
- On Venice this endpoint covers generation and upscaling; the companion Qwen-Image-Edit checkpoint that handles image editing is a separate model.
- Closed rivals such as GPT Image 2 and Flux 3 push higher maximum resolutions and newer feature sets — the Qwen team has since shipped 2.x and 3.0 successors.
Use cases
What it is good for
- 01Posters, signage, and packaging where headline copy must be spelled correctly.
- 02Bilingual or Chinese-language marketing assets that other models routinely garble.
- 03Infographics and diagrams generated straight from a written brief.
- 04Self-hosted or fine-tuned pipelines — take the Apache 2.0 weights and run them on your own infrastructure.
- 05Cost-effective iteration at $0.03 per image, with 2×/4× upscaling reserved for final selects.
Prompting
Getting better results
Wrap the exact on-image text in quotes — e.g. a chalkboard sign reading "Qwen Coffee — $2 per cup" — so the renderer treats it as typography, not scenery.
Write Chinese characters directly in the prompt rather than romanized pinyin; logographic rendering is this model's signature strength.
Append the official quality suffix from Qwen's examples — ", Ultra HD, 4K, cinematic composition." — to lift composition and detail.
Choose the aspect ratio deliberately: eight presets from 21:9 cinematic to 9:16 vertical are available, and text layouts behave very differently across them.
Front-load text instructions in the first few hundred characters — the 2,048-character limit fills fast on layout-heavy briefs.
Iterate at base resolution, then spend $0.02 (2×) or $0.08 (4×) on upscaling only the winning frame.
Samples
Sample outputs
Generated on Venice with our standard prompt suite — the same prompts we run through every model of this type, so you can judge it like-for-like.
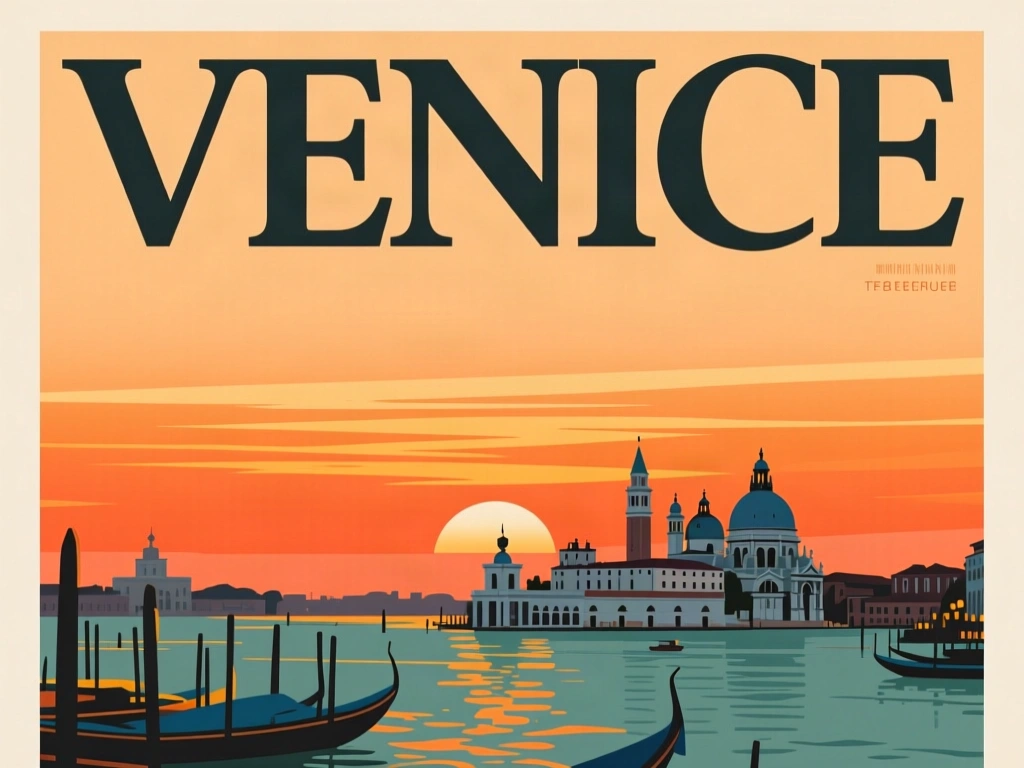
A retro travel poster with the bold headline "VENICE" in large condensed serif type, sunset color palette, clean layout
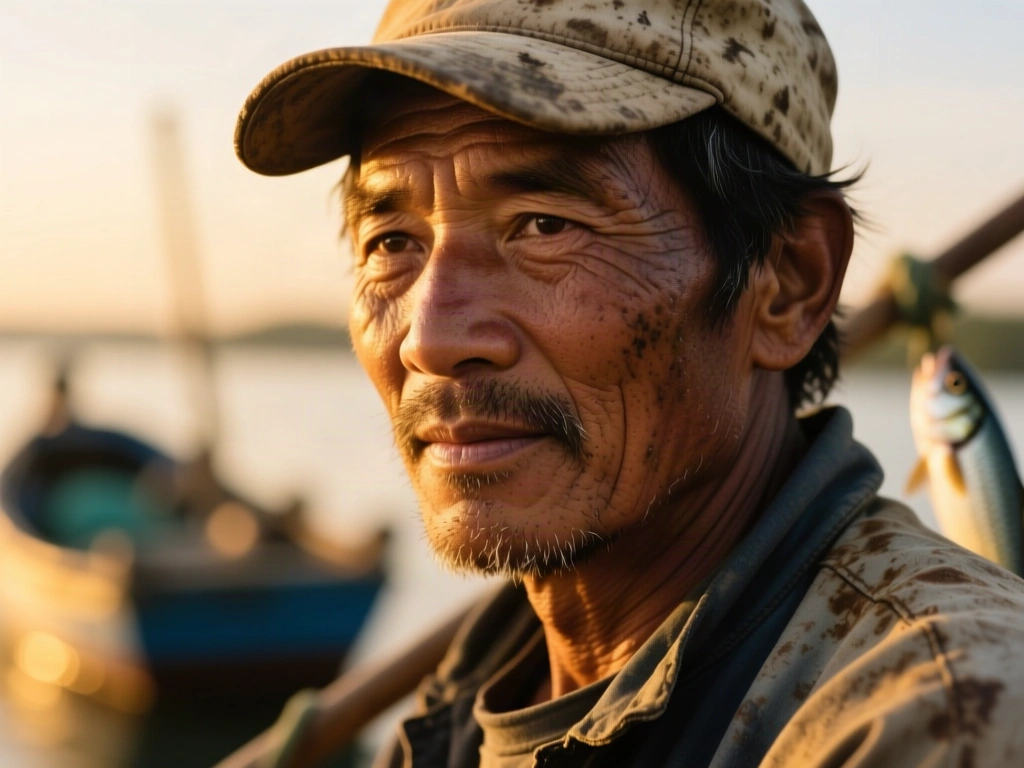
Photorealistic close-up portrait of a weathered fisherman at golden hour, 85mm lens, shallow depth of field, natural skin texture
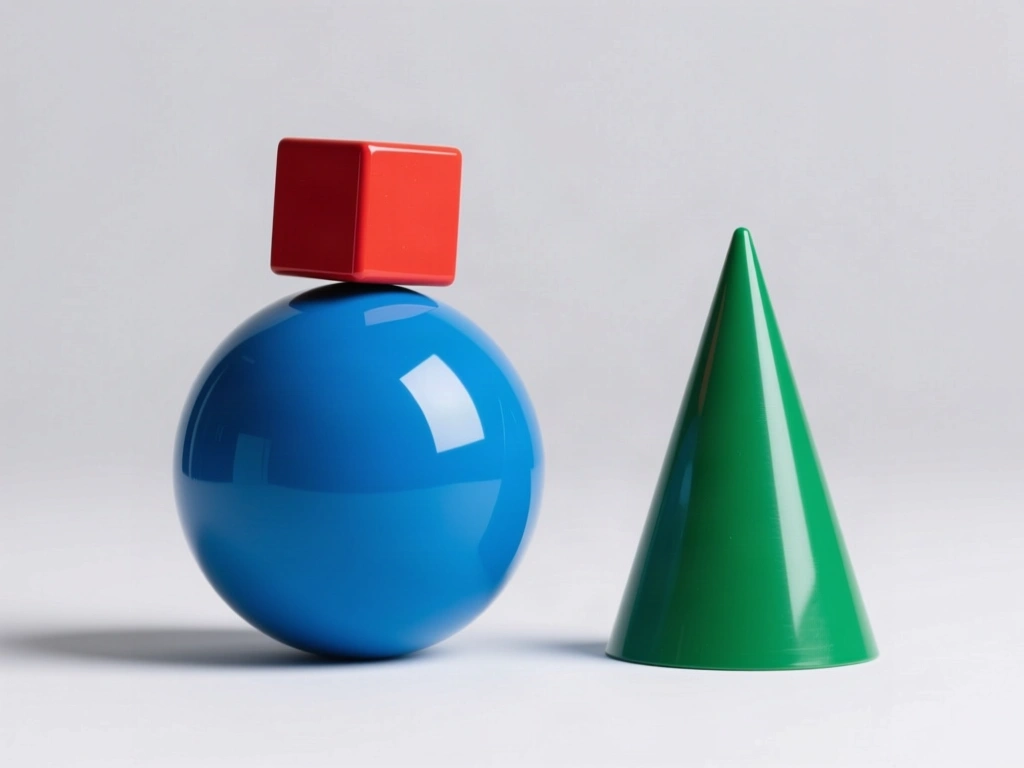
A small red cube balanced on top of a large glossy blue sphere, with a green cone to the right, plain light-grey studio background
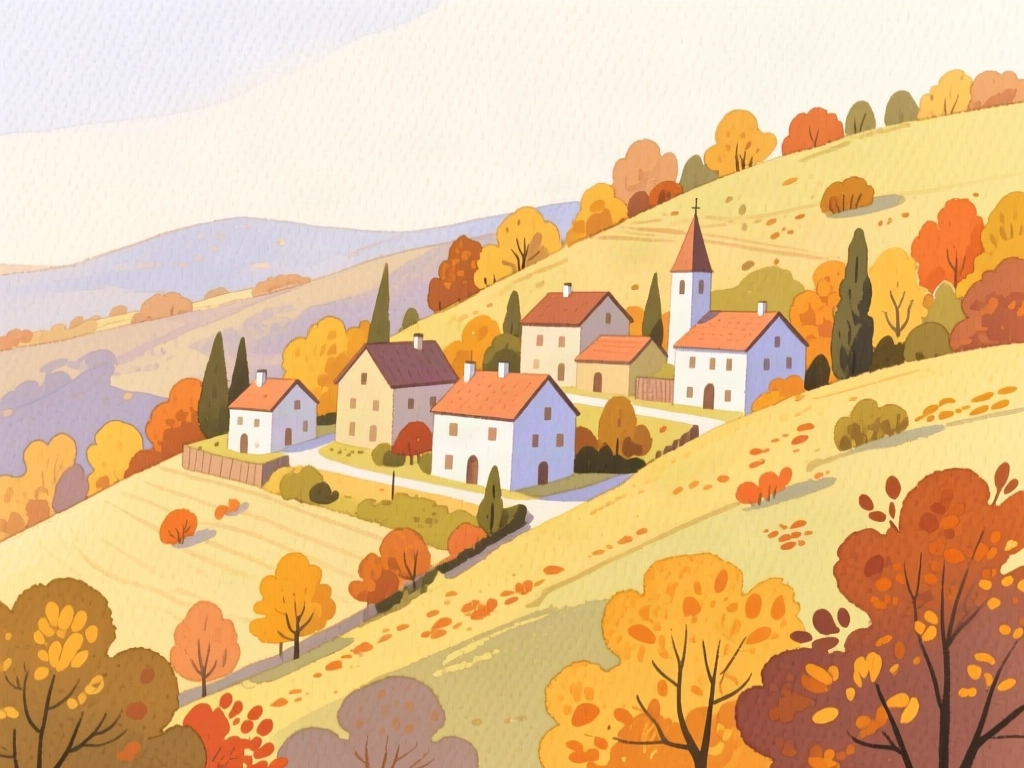
Cozy watercolor illustration of a hillside village in autumn, warm tones, soft paper texture
Alternatives
How it compares
| Model | Best for | Max resolution | Open weights | Price (Venice) |
|---|---|---|---|---|
| Qwen Image | In-image text & open weights | up to 2K | Yes | $0.03 / image |
| Chroma | Cheapest open drafts | — | Yes | $0.01 / image |
| Flux 2 Max | Photoreal detail | — | No | $0.09 / image |
| GPT Image 2 | Instruction following at 4K | 4K | No | from $0.27 / image |
| Krea 2 Turbo | Fast open-weight iteration | 2K | Yes | from $0.04 / image |
Pick Qwen Image when the image has to carry accurate words — especially bilingual or Chinese copy — and you want Apache-licensed open weights at a flat $0.03. For closed-model 4K polish, GPT Image 2 is the alternative; for the cheapest open drafts, Chroma.
API
Call it from your code
Venice exposes this model through the REST API. Queue a generation with the model id.
curl https://api.venice.ai/api/v1/image/generate \
  -H "Authorization: Bearer $VENICE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen-image",
    "prompt": "A serene mountain lake at dawn, photorealistic"
  }' --output image.png
Pricing
What it costs on Venice
Flat per-image pricing on Venice: $0.03 per generation.
New Venice accounts include a free daily allowance and 500 welcome credits — no credit card required.
FAQ
Frequently asked questions
Qwen Image is Alibaba's 20B MMDiT text-to-image foundation model, released on August 4, 2025. It is built around complex text rendering — multi-line layouts, paragraph-level semantics, and logographic scripts like Chinese — and uses a dual-encoding Qwen2.5-VL/VAE architecture designed for precise image editing.
Venice charges a flat $0.03 per generation, with 2× upscaling at $0.02 and 4× upscaling at $0.08. There is no subscription required — you pay per image in credits.
Yes on both counts as a model: the weights are public on Hugging Face under the Apache License 2.0, which permits self-hosting, fine-tuning, and commercial use. On Venice you can try it with the platform's free daily prompts before paying per image.
Yes — Chinese text rendering is its standout capability. The Qwen team trained it with a progressive text-rendering curriculum, and it outperformed existing state-of-the-art models by a significant margin on Chinese text benchmarks (LongText-Bench, ChineseWord, TextCraft) per the official technical report. English and other alphabetic scripts are also handled at a high level.
The Qwen-Image family includes a dedicated Qwen-Image-Edit checkpoint for image-to-image editing, and the base model's dual-encoding design was built with editing consistency in mind. On Venice, however, this endpoint exposes generation and upscaling — the editing checkpoint is a separate model.
Qwen Image wins on in-image typography, open Apache 2.0 weights, and price ($0.03 vs $0.09). Flux 2 Max is the stronger pick for photographic realism and closed-model polish. If your image contains readable text, Qwen Image is the safer bet.
Eight presets: 1:1, 3:2, 16:9, 21:9, 9:16, 2:3, 3:4, and 4:5 — covering cinematic, portrait, social, and print-style framing.
Venice runs Qwen Image under its anonymized privacy tier: prompts are not stored, profiled, or used for training, and generations carry no personal account history. You can use it in the Venice app or through the Venice API without building a generation profile.
No — Venice does not classify Qwen Image as an uncensored model, so standard content filtering applies. If filter-free output is the priority, some other open models on Venice are better suited; if typography and open weights are the priority, Qwen Image remains the strongest option.
Use Qwen Image anonymously
Venice does not store your prompts. Chat history stays in your browser.